Observability Platform
End-to-End Observability for Modern Enterprises
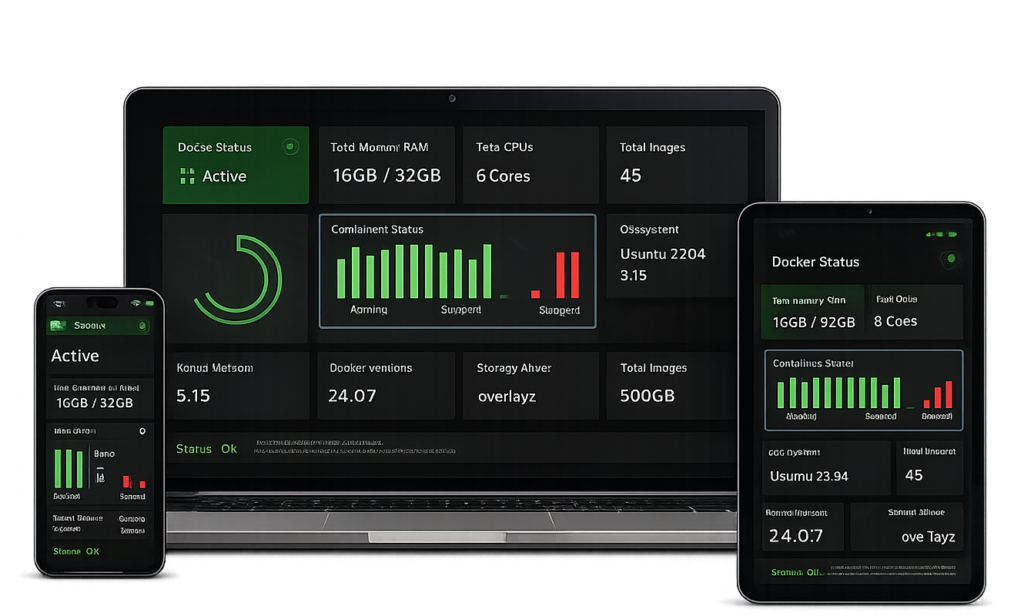
Our platform empowers organisations with end-to-end visibility across their entire tech ecosystem. From infrastructure, applications, containers to cloud-native and on-premises environments, it delivers real-time monitoring, intelligent analytics, and automated problem remediation.
Monitor
Analyze
Optimize
System Monitored
0
+
Uptime Monitoring
0
%
Features
Powerful features for end-to-end monitoring
Monitor
Real-time visibility across every layer
Analyze
Three layers of intelligent monitoring
Optimize
Auto-remediation and improvements
Monitoring
Our Monitoring Coverage
- Production Servers
- UAT Servers and DR Set up
- Network Devices
- Cloud & On-Prem & VPN-connected remote locations.
Agent-Based Monitoring
Deploy a lightweight agent on your servers and endpoints to collect deep, real-time metrics across every layer of your environment.
Infrastructure Metrics
CPU, memory, disk, network interface stats
Application Performance
Response times, error rates, throughput
Agentless Monitoring
Monitor devices and systems without installing any software ideal for restricted environments and network infrastructure.
SNMP
Protocol
SSH
Protocol
ICMP
Protocol
WMI
Protocol
Network Device Monitoring (SNMP-Based)
Our network monitoring framework ensures comprehensive visibility and proactive management of all critical network infrastructure components.
We continuously monitor switches, routers, firewalls, load balancers, and storage devices to maintain optimal performance, availability, and security across the environment.
SNMP v1/v2c/v3
Protocol Support
Load Balancers
Pool health, session counts
Switches
Port utilization, VLAN, STP
Alert Framework
Intelligent Alert Management
Threshold-based alerting with multi-level severity classification ensures the right team gets notified at the right time no alert fatigue.
Alert Coverage
- CPU & Memory thresholds
- Disk I/O and storage
- Network latency spikes
- Application error rates
- Service availability
Critical
Immediate action required. Service is down or severely degraded. Auto-escalate to on-call team and create priority ticket.
High
Urgent attention needed. Performance significantly degraded but service still operational. Notify primary responders.
Medium
Monitor closely. System showing signs of stress. Notify team for review and preventive action during business hours.
Low
Informational. Non-urgent anomaly detected. Log for trend analysis and review in next operational cycle.
Our Process
How it Works ?
01
Collect
Metrics, logs, traces across all environments.
02
Analyze
Automated insights & root-cause detection.
03
Alert
Smart alerts, remediation, continuous improvement.
Case Study
Magic Behind Our IT Solutions
We begin by conducting a comprehensive needs assessment to understand your specific requirements, challenges, and goals.
Enhancing Healthcare Platform Reliability
Our recent projects in the healthcare sector demonstrate our ability to deliver proactive monitoring and performance stability for high-availability systems.
Leading healthcare platforms required continuous uptime, real-time monitoring, and compliance with health data standards. They faced issues such as fragmented server environments, single points of failure, API slowdowns, and limited visibility into containerized infrastructures.
We implemented a comprehensive observability strategy using monitoring agents across servers and containers. Synthetic checks, real-time log analysis, API performance tracking, and automated alerting systems were set up. These solutions were integrated with intelligent ticketing tools to streamline incident resolution and ensure compliance.
Both platforms achieved near-perfect uptime, faster issue detection, and enhanced operational visibility. Automated monitoring reduced manual efforts, improved response times by up to 90%, and significantly increased the reliability of patient-facing services. infrastructures.